Prompt Quality Dimensions Guide for Engineers
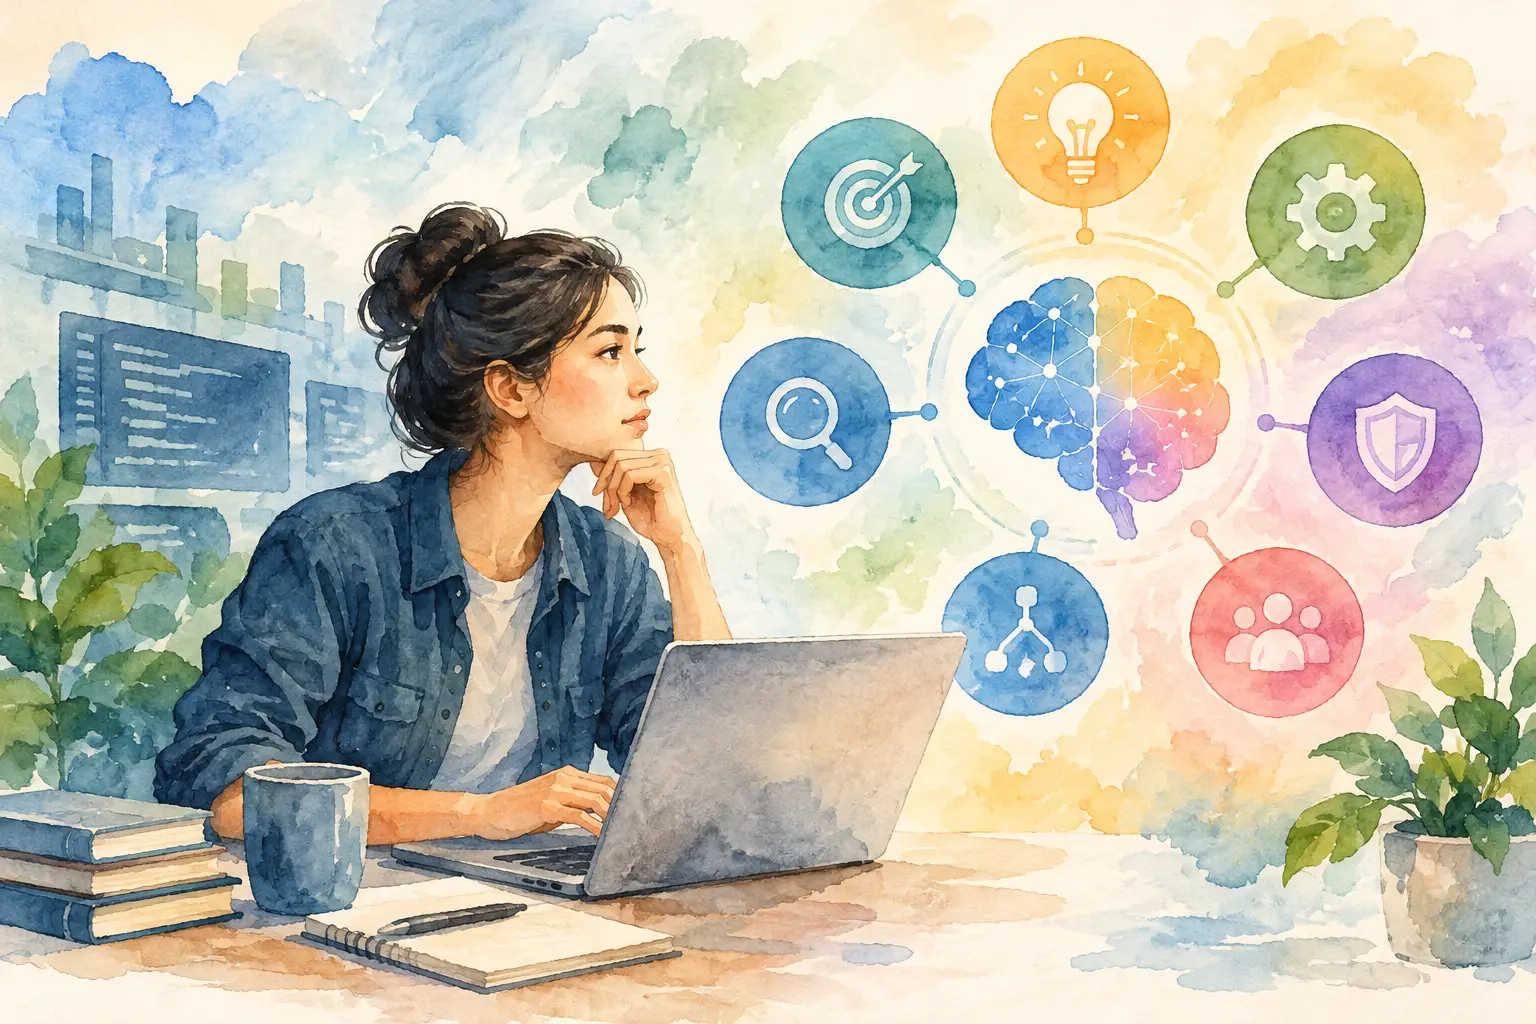
A prompt can be grammatically clean and still fail in production. The usual failure is not that the model ignored an instruction. The request left too much room for interpretation, mixed competing goals, or gave no way to check the result. This prompt quality dimensions guide treats a prompt as an interface contract: it defines the job, the available inputs, the boundaries, and the acceptable result.
That distinction matters when prompts move beyond one-off chat use. A prompt inside a code review workflow, support tool, data pipeline, or agent loop needs behavior you can inspect and revise. You are not measuring whether the prose sounds persuasive. You are measuring whether another system can perform a defined task with bounded ambiguity.
Prompt quality is separate from model output quality
A good output can come from a weak prompt. A capable model may infer missing context, choose a sensible format, and avoid an edge case by chance. That does not make the prompt dependable. Run it against a different model, a longer input, or a less common case, and the missing instruction becomes visible.
The reverse is also true. A well-specified prompt can produce a poor answer when the source material is wrong, the model lacks the required capability, or the task needs a tool it cannot access. Prompt quality is one input to system quality, not a substitute for evaluation.
This is why prompt review should ask two separate questions. First: can a reader identify the intended behavior from the prompt alone? Second: did the system produce a correct result on representative cases? The first catches specification defects. The second catches model, retrieval, tool, and data defects.
The six dimensions to score
Use a small rubric that reviewers can apply consistently. A 0 to 3 scale is enough: 0 means absent or contradictory, 1 means present but materially incomplete, 2 means usable with known ambiguity, and 3 means explicit and testable. A total is useful for triage, but the lowest score matters more than the average. A prompt with clear prose and no output contract is not ready because its average looks acceptable.
| Dimension | What you inspect | What a high score looks like | | --- | --- | --- | | Task definition | The action and decision requested | One primary job, stated in operational terms | | Context and inputs | Facts, source boundaries, and definitions | The model knows what it may use and what each input means | | Constraints | Rules, exclusions, priorities, and scope | Conflicts are resolved and limits are explicit | | Output contract | Format, fields, length, and audience | A consumer can parse or use the result without guessing | | Verification | Evidence, checks, and uncertainty handling | The result shows how claims were supported or flags gaps | | Feasibility | Model, tools, data, and time available | The request matches what the system can actually do |
1. Task definition
“Review this pull request” is not a task definition. It might mean find correctness bugs, assess style, explain the architecture, or decide whether to merge. Those are different jobs with different acceptable outputs.
A stronger instruction names the action and the unit of work: “Identify changes that can cause a runtime failure in the supplied diff. Do not comment on naming or formatting.” The reviewer now has a target and a boundary.
Ask whether the prompt has one primary objective. Multiple objectives are valid, but they need an order. “Summarize the incident, identify the root cause, and propose fixes” should say whether the root-cause claim needs evidence before recommendations, and whether a missing root cause should stop the response. Otherwise the model will choose its own ordering.
2. Context and inputs
Models do not know which facts in your system are stable, which files are authoritative, or which terms have local meanings. Put that information in the prompt or provide it through a controlled retrieval step.
Context is not the same as adding every available document. Excess material can hide the relevant facts, increase cost, and introduce contradictory instructions. Give the minimum source material needed to make the decision. State its boundaries: “Use only the issue text and diff below. Do not infer behavior from files not included.”
Definitions deserve the same care. If “owner” means the person who made the most changes in the last 90 days rather than the GitHub repository owner, say so. Terms that look obvious are often where scoring drifts.
3. Constraints and priorities
Constraints make a request safe and repeatable. They cover prohibited actions, scope, tone, privacy rules, budget, and refusal behavior. They also establish what wins when rules compete.
Consider a support drafting prompt that says to be concise, include diagnostic steps, and never request secrets. It still needs a priority when the diagnostic step requires sensitive material. State the rule directly: ask for redacted logs or a non-sensitive identifier instead. Do not merely say “follow security best practices.”
Avoid constraints that cannot be observed. “Be accurate” is a goal, not an instruction a reviewer can score. Replace it with a process requirement: cite the provided source section for each factual claim, or label claims unsupported by the supplied material.
4. Output contract
Output format is where otherwise useful prompts often fail integration. A human may tolerate an answer with three extra paragraphs. A downstream parser, ticket template, or UI component may not.
Specify the shape the consumer needs. For structured output, define field names, allowed values, and whether omitted data should be null, an empty list, or a stated uncertainty. For prose, set the audience, maximum length, and required sections. If JSON is required, say whether markdown fences are forbidden. This small detail prevents a common parsing failure.
Do not over-specify presentation when the result is read by a person and judgment matters. A strict schema can force weak evidence into confident-looking fields. The right contract depends on the next step in the workflow.
5. Verification and uncertainty
A prompt should tell the model what to do when evidence is absent. Without that instruction, models often fill gaps with a plausible completion. The result may read well and still be wrong.
Require a check that fits the task. For source-grounded answers, require references to source IDs or quoted excerpts. For code analysis, require the file and line range plus the failure path. For classification, require confidence only if you define what confidence represents and how it will be calibrated.
“Do not hallucinate” is not a usable verification method. “If the supplied material does not establish a claim, write insufficient evidence and name the missing input” is. It gives the system a permitted failure mode.
6. Feasibility
Some prompt defects are really system design defects. Asking a text-only model to verify a current package vulnerability without an attached advisory source cannot work. Asking an agent to modify a repository without write access cannot work. No wording fixes missing capabilities.
Check the execution environment before you score the prompt. Which model runs it? What tools can it call? Which tool results are available? What is the context limit? Is the output consumed by code or a person? These constraints determine whether the specification is achievable.
Apply the rubric before you tune wording
Start with a baseline prompt and score each dimension independently. Do not rewrite it while scoring. That preserves the original failure mode and makes later changes measurable.
Then fix the lowest dimension first. If the output contract scores 0, changing “analyze” to “carefully analyze” is wasted work. Add a concrete result shape, rerun the same evaluation set, and record what changed. Continue until the prompt has no unbounded dimension that can cause a material failure.
Use representative cases, not only happy paths. Include a complete input, a sparse input, conflicting source material, an out-of-scope request, and an input that should produce insufficient evidence. If the prompt is used for code, include generated code, dependency changes, and a diff with no bug. A system that always finds a problem is not a useful reviewer.
For recurring work, keep the rubric alongside the prompt version and test set. Wizhut Research's Promptivo explores deterministic prompt scoring without an LLM, which is useful as a direction: prompt checks should be repeatable enough to compare revisions. Deterministic checks will not judge every semantic choice, but they can catch missing sections, conflicting rules, vague verbs, and absent output requirements before an expensive run.
A worked prompt revision
Suppose a team begins with: “Review this diff and tell me if it is safe.” It scores poorly because “safe” has no local definition, the allowed evidence is unclear, and the response shape is unspecified.
A revised version might say: “Review the supplied unified diff for defects that can cause a production runtime error, data loss, or authorization bypass. Use only the diff and repository notes below. Report at most three findings. For each finding, provide severity as high, medium, or low; file and line range; failure scenario; and a specific fix. If the diff does not provide enough evidence, return an empty findings array. Do not report style, naming, or test coverage concerns.”
This does not guarantee correctness. It does make errors easier to investigate. A false positive can be traced to the evidence rule or severity definition. A missed issue can be traced to the task scope, missing context, or model limitation. That is the practical value of quality dimensions: they turn “the prompt feels weak” into a defect you can name and test.
Treat each prompt change like an interface change. State what behavior you expect to change, run the cases that exercise it, and keep the failure case when it teaches you something. The goal is not a prompt that sounds precise. The goal is behavior your team can rely on when the input is less cooperative than the demo.
 Promptivo